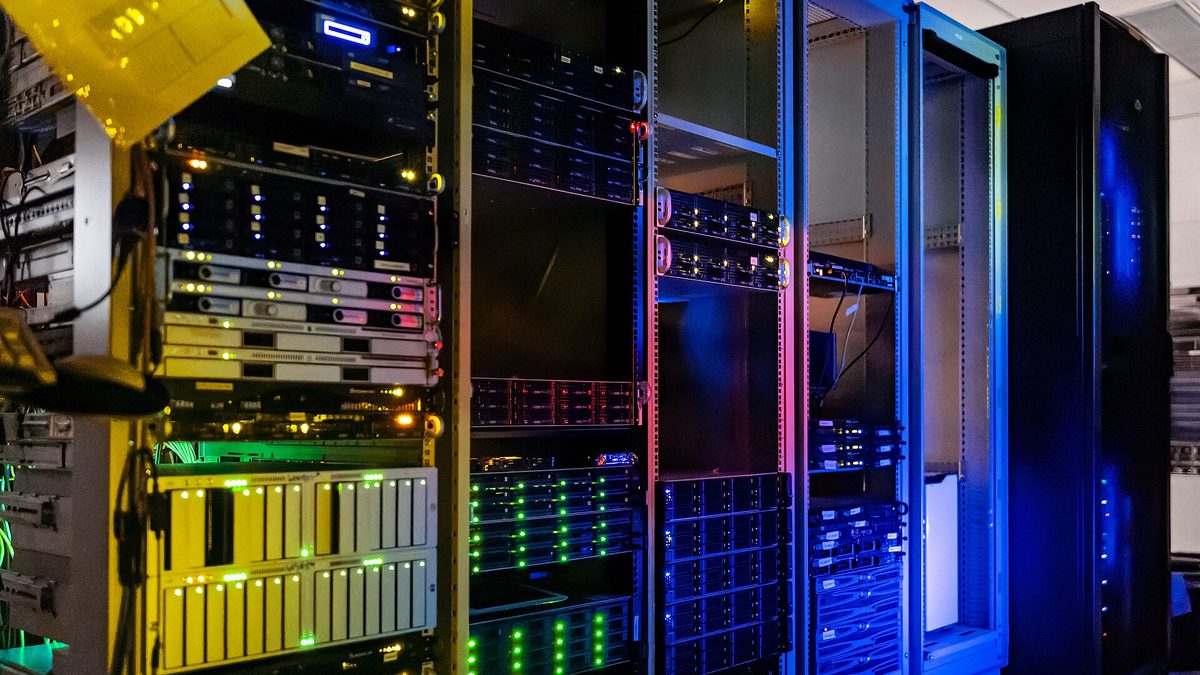
Cloud AI requires specialized distributed architecture. A large model is rarely a good fit for one ordinary server. Training and serving often need many GPUs, fast links between them, shared storage, and software that can manage the whole group.
That changes the design problem. Cloud AI is not simply a model placed inside a virtual machine. The system must move data, model weights, and requests across many parts without wasting the expensive compute.
I keep the main idea simple: the GPUs do the math, but the network often decides how well the system works.
The hard part is moving information
During model training, each GPU works on part of the job. After a step, the GPUs must share updates. These updates are often called gradients. The system uses them to keep the model in sync.
This creates heavy traffic between servers. The traffic does not move only from users to the cloud. Much of it moves between machines inside the same cluster. This is known as east-west traffic.
A normal web service may send a request to one server and receive a reply. A distributed AI job may send data between many GPUs for every training step. A slow link can leave GPUs waiting. Fast processors then spend time idle.
The same issue appears during inference. Inference means using a trained model to produce an answer. Some models fit on one accelerator. Larger models may need several GPUs or several servers. The service must treat those parts as one working unit.
That requires more than a GPU count. It requires a network with low delay and high bandwidth. It also requires software that can place related tasks together and restart them as a group when a machine fails.
A cloud AI system has several layers
The first layer is compute. Cloud providers offer machines with GPUs or other accelerators. These machines may be grouped into nodes, which are individual servers in a cluster.
The second layer is the network. It connects the accelerators and carries model data, gradients, requests, and results. For distributed work, network design is part of model performance.
The third layer is storage. Training data may sit in object storage, a shared file system, or another data service. The system must feed data to the GPUs fast enough. It also saves checkpoints, which are copies of model state used to resume training.
The fourth layer is orchestration. An orchestrator places workloads on machines and watches their state. Kubernetes is one example. It can manage containers, GPU resources, services, and groups of related tasks.
The final layer is the serving system. It receives requests, routes them to models, scales workers, and handles failed instances. Training and inference have different needs, so they often use different pools of machines.
This separation matters. Training may run for hours or days and can sometimes use machines that are cheaper but less reliable. Inference must respond to live requests. It needs stable latency and enough spare capacity for sudden demand.
One cluster can support both jobs, but mixing them without rules creates trouble. A training task can consume the GPUs that an inference service needs. Good systems use scheduling rules, separate node pools, or separate clusters.
Data placement can decide the design
A model may be ready, while its data is not. Large datasets can sit far from the GPU cluster. Moving them can take time, cost money, and add more failure points.
This is why cloud AI architecture often tries to keep compute near data. In some cases, data is copied into the cloud region where training runs. In other cases, a distributed data layer gives GPUs access to data across sites.
Neither choice is free. Copying data adds storage and sync work. Reading data across regions adds network delay and transfer cost. Keeping data in place can simplify ownership, but it may make the training path harder to tune.
The model also needs its own state. During training, checkpoints can be large. During inference, model weights may need to load into GPU memory before requests can run. A service that reloads weights too often may spend more time preparing than answering.
These details explain why cloud AI needs architecture built for the full data path. The model is only one part of the system.
Cloud does not remove hardware limits
Cloud platforms make specialized hardware easier to rent. They do not remove the limits of memory, network speed, or power.
A model that does not fit on one GPU must be split. This may mean dividing the data across GPUs or dividing the model itself. Each method adds coordination work.
Data parallelism gives different GPUs different batches of data. The GPUs then share updates. Model parallelism splits the model across devices. Each request may need to cross several devices as it moves through the model.
The right choice depends on the model, request size, batch size, and response time. There is no single design that wins for every workload.
Failure also becomes normal at larger scale. More machines mean more parts that can fail. A useful system needs checkpoints, health checks, retries, and clear recovery rules. A job that loses one worker should not always lose all of its progress.
That recovery logic can be harder than the first model code. It also needs testing under real load. A system may look correct with one node and behave very differently with many nodes.
The cloud adds useful flexibility
Specialized architecture does not mean cloud AI is impractical. The cloud can provide access to accelerators, managed storage, networking, and orchestration without requiring every team to own a data center.
It can also support different locations. A service may run inference near users while keeping training in a central region. This can reduce response delay and help keep data within required boundaries.
But distributed cloud design adds its own cost. GPU time is expensive. Cross-region traffic can be expensive. Idle capacity is wasteful. Complex systems also need people who understand both machine learning and production operations.
This is where many simple cloud AI plans fail. They count accelerators but ignore traffic, storage, scheduling, and idle time. The result may be a large cluster with poor use of its compute.
The main limit is that the best architecture is still workload-specific. Public cloud documentation can describe supported services and patterns. It cannot guarantee the right design for every model, dataset, or traffic shape. Performance must be measured for the actual system, and future hardware may change the trade-offs.
My practical view is direct. Start with the smallest architecture that matches the model. Add distributed training or multi-node inference when the model size, data volume, or service demand requires it. Every added node creates another path for delay and failure.
Cloud AI works when the whole path is designed together: data, storage, network, accelerators, orchestration, serving, and recovery. The model may be the part that gets attention, but the distributed system decides whether that model can work at useful scale.
That is the kind of practical detail The Model Log is meant to keep in view: one AI concept, one working example, and one honest look at what actually works.